Most comprehensive guide, created for all Web Scraping developers.
Scrapeless offers AI-powered, robust, and scalable web scraping and automation services trusted by leading enterprises. Our enterprise-grade solutions are tailored to meet your project needs, with dedicated technical support throughout. With a strong technical team and flexible delivery times, we charge only for successful data, enabling efficient data extraction while bypassing limitations.
Contact us now to fuel your business growth.
Provide your contact details, and we'll promptly reach out to offer a product demo and introduction. We ensure your information remains confidential, complying with GDPR standards.
Your free trial is ready! Sign up for a Scrapeless account for free, and your trial will be instantly activated in your account.
This guide demonstrates how to build a production-grade price-drop alert system by combining Scrapeless Scraping Browser's anti-detection cloud rendering with a simple Python pipeline that extracts prices from the populated DOM, stores them in an append-only log, compares against the previous low, and fires webhooks on drops. The result is a scalable monitoring system that works across most public product pages, handles regional pricing variations through geo-pinned proxies, and runs unattended on any scheduler—proving that real-time price tracking requires rendering, not just HTTP requests.
 Ethan Brown

This guide shows you how to reliably extract Walmart product data, competitive pricing, and inventory information without hitting anti-bot walls or getting bot-check pages disguised as HTTP 200 responses. Learn why generic proxies fail on Walmart, and discover how rendered cloud browsers with residential egress and session persistence deliver the actual product grid you need for price tracking, MAP compliance monitoring, and catalog ingestion at scale.
Ethan Brown
This guide walks through the session warm-up pattern that bypasses eBay's search endpoint protections, so you can collect pricing and availability data reliably and feed it into repricing rules, brand-protection workflows, or AI-powered product research. Build a production-grade eBay monitoring pipeline that tracks competitor prices, detects unauthorized listings, and captures geo-specific product data—all without hitting eBay's anti-detection walls.
 Emily Chen

Track competitor prices across 5,000 SKUs and 8 competitors in 4 markets daily by building a scalable pricing pipeline that renders each product page through Scrapeless with market-specific egress, extracts prices into a normalized schema, and streams the results to your warehouse for real-time repricing decisions. The architecture separates collection (render → extract → normalize) from decision-making (diff → alert), so your pricing rules stay stable even when retailers rotate their DOM.
Ethan Brown
Eight free web scrapers ranked across five dimensions—JavaScript rendering, proxy access, anti-detection handling, and real usage ceilings. Whether you're a non-developer needing a visual scraper, a Python engineer building a long-term crawler, or an AI agent calling an API on demand, this guide shows which tool fits your workload and where each one stops being free.
 Isabella Garcia

Async Python web scraping is 10-100× faster than synchronous approaches by leveraging asyncio's event loop to handle hundreds of concurrent HTTP requests on a single thread. This guide covers the complete pattern: using aiohttp with Scrapeless residential proxies for HTTP-tier fetches, and escalating JavaScript-rendered pages to Scrapeless Scraping Browser via Playwright's async API. Learn how to build production-grade scrapers with proper concurrency control, failure handling, and tiered architecture across 7 practical steps and working code examples.
Ethan Brown
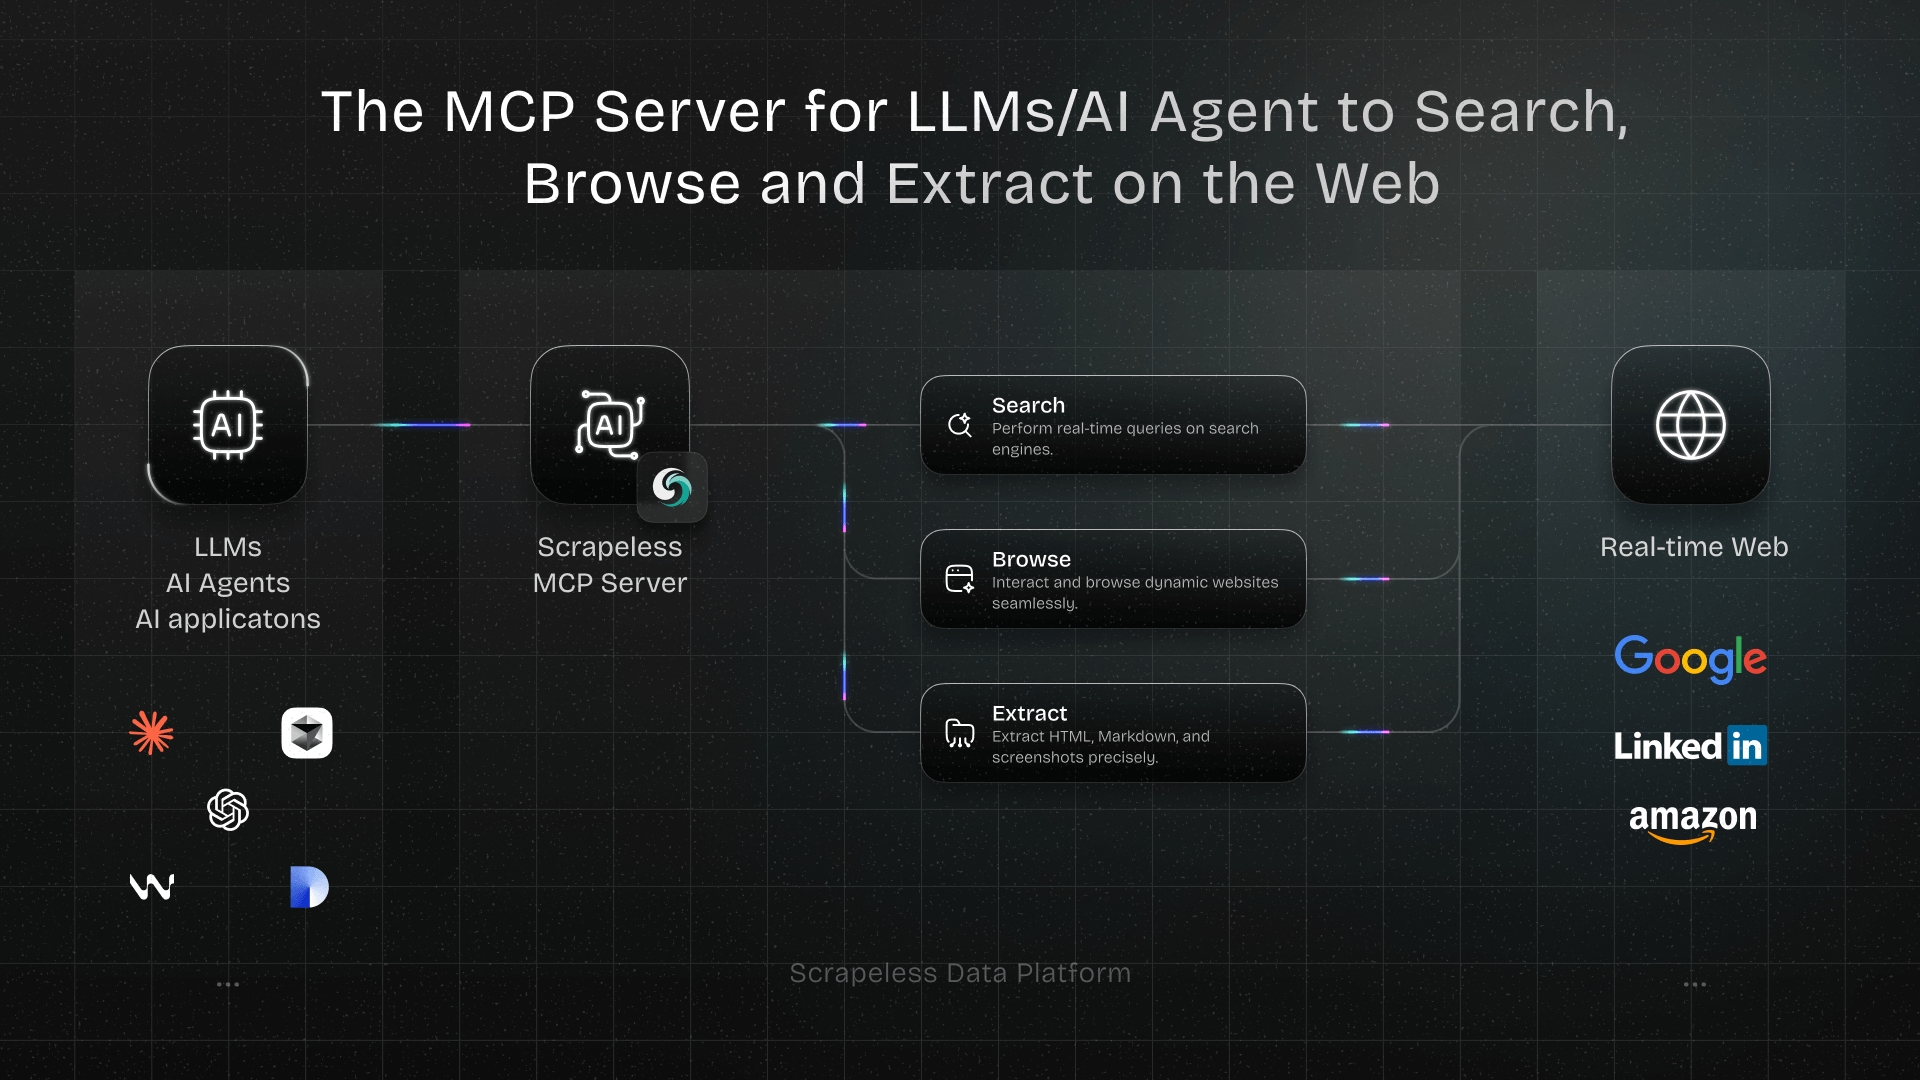
This post closes that gap by wiring the Scrapeless MCP server into GitHub Copilot CLI. One config block gives the agent Google search, JavaScript rendering, and a full cloud browser, all reachable through the same natural-language prompts it already takes for code.
Ethan Brown
Discover which rotating proxy provider delivers the best value for your scraping needs. We benchmark Scrapeless, Decodo, Oxylabs, SOAX, NetNut, Webshare, IPRoyal, DataImpulse, Rayobyte, and Infatica across success rates, latency, pool size, and pricing to guide your decision.
Emily Chen