Most comprehensive guide, created for all Web Scraping developers.
Scrapeless offers AI-powered, robust, and scalable web scraping and automation services trusted by leading enterprises. Our enterprise-grade solutions are tailored to meet your project needs, with dedicated technical support throughout. With a strong technical team and flexible delivery times, we charge only for successful data, enabling efficient data extraction while bypassing limitations.
Contact us now to fuel your business growth.
Provide your contact details, and we'll promptly reach out to offer a product demo and introduction. We ensure your information remains confidential, complying with GDPR standards.
Your free trial is ready! Sign up for a Scrapeless account for free, and your trial will be instantly activated in your account.
Hermes Agent's browser tool speaks Chrome DevTools Protocol natively—wire it to Scrapeless Scraping Browser with one config line for residential proxies, JS rendering, and anti-bot fingerprinting in 195 countries. This post walks through the setup, prompts, and discover→extract patterns that make chat-driven research, lead gen, and monitoring workflows production-ready across Telegram, Discord, or CLI.
 James Thompson

This blog post explains why bare LLMs fail for real-time agentic workflows like price intelligence and market monitoring, then demonstrates how Scrapeless Scraping Browser + LangChain tools solve proxy, JS rendering, anti-detection, and session challenges. It walks through building a complete **Discover → Render → Extract → Store** AI data pipeline with a competitive research example, Pydantic outputs, concurrency controls, and observability.
 Isabella Garcia

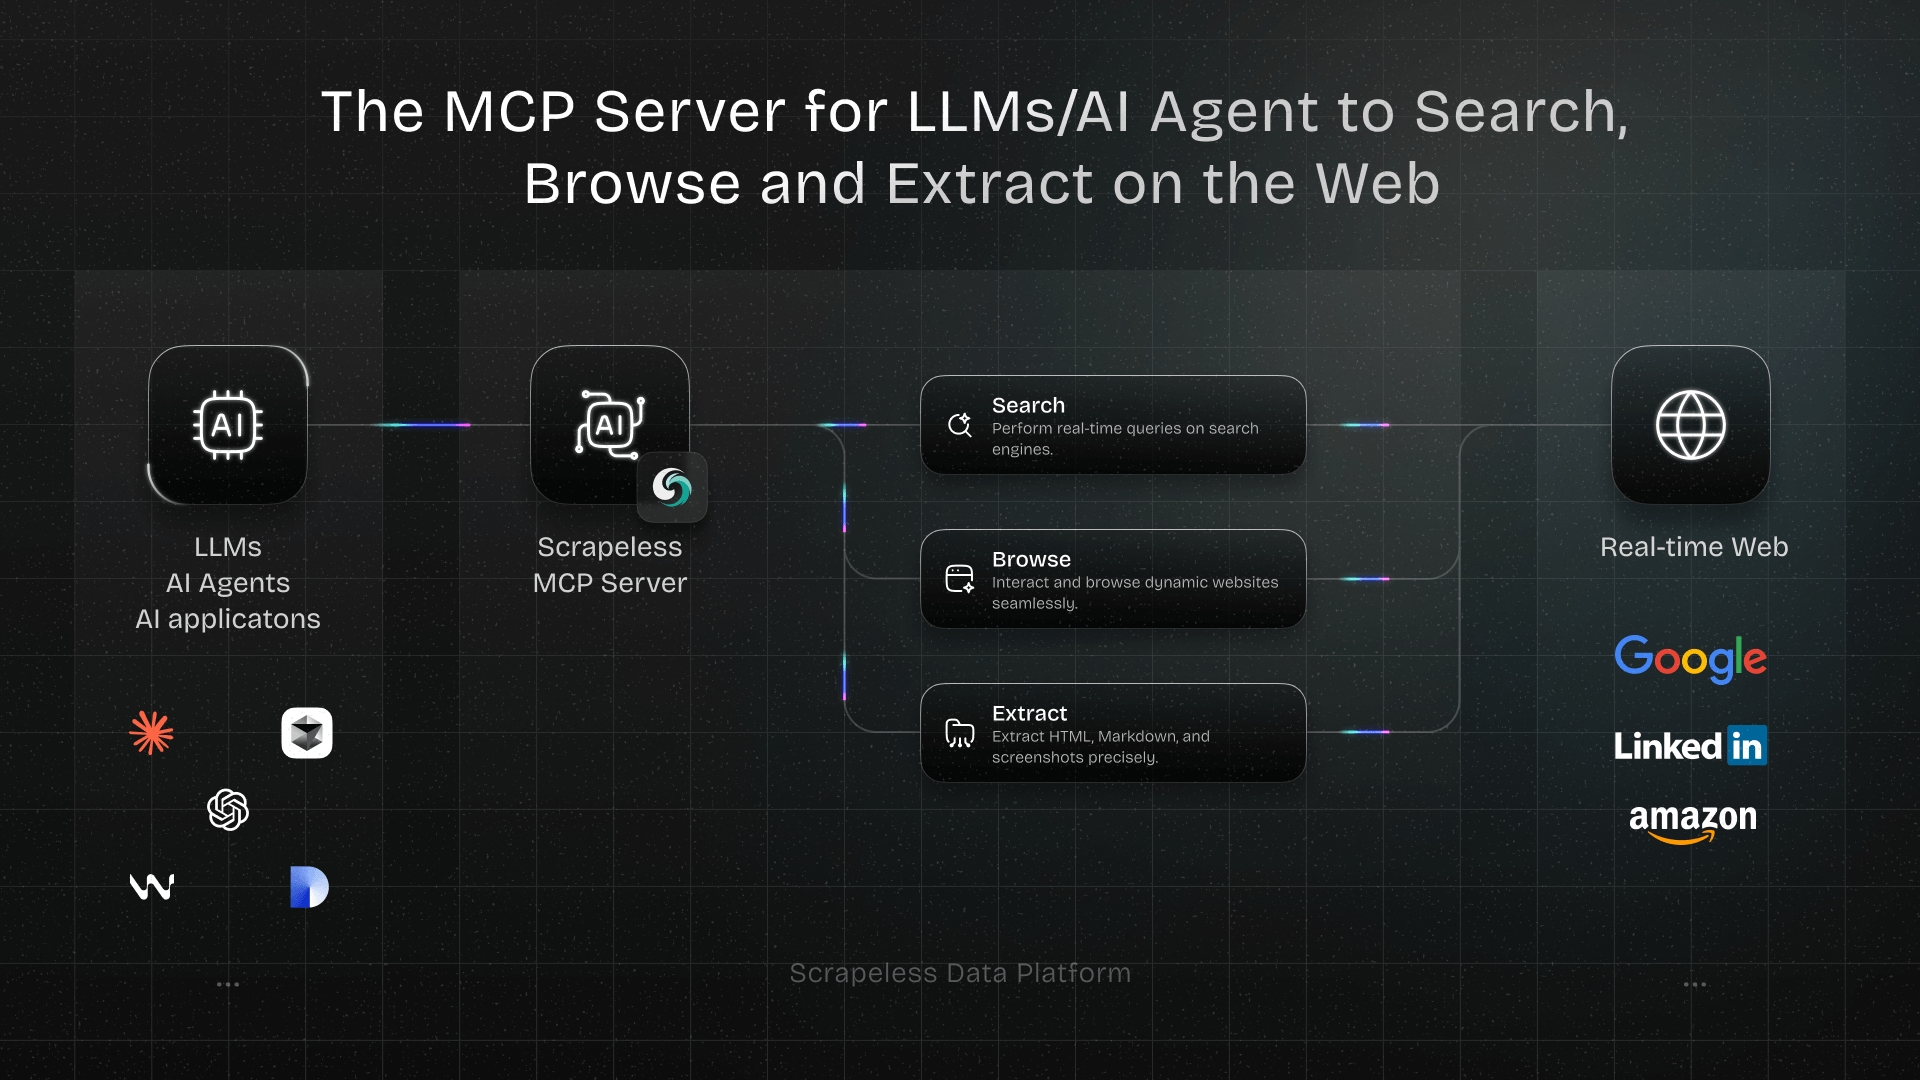
This post walks through using the **Scrapeless MCP Server** with any **MCP-aware client** — Claude Desktop, Claude Code, Cursor, OpenAI Codex CLI, Gemini CLI, or a custom client built against the [MCP TypeScript SDK](https://github.com/modelcontextprotocol/typescript-sdk) — to scrape Google Maps end to end. The server wraps **Scrapeless Scraping Browser** — an agent-ready cloud browser — as a set of MCP tools, so the agent calls `browser_create` / `browser_goto` / `browser_scroll` / `browser_get_html` directly through the protocol rather than shelling out to a CLI or wiring up an SDK. The cloud browser handles the rendering, the proxies, and the anti-detection layer; the agent handles the discover → extract pattern.
 Ethan Brown

This post walks through a terminal-first workflow on top of Scrapeless Scraping Browser — an agent-ready cloud browser that handles JavaScript rendering, residential-proxy egress, and session-bound state for per-store stock checks. Steps 1–8 below cover the full PDP extraction (JSON-LD fast path + hydrated fields), search/category pagination, the location-selector flow that unlocks store-specific availability, and the review pipeline (top-10 from JSON-LD plus rendered-DOM pagination, sort, and filter).
 Ava Wilson

Scrapeless Amazon Rufus Scraper API removes the hardest parts of working with Rufus. Instead of managing Amazon login sessions, SSE parsing, anti-bot challenges, and marketplace routing yourself, you send one request and get structured output back. That makes it a practical choice for production pipelines that need reliable, scalable access to Rufus-generated shopping intelligence.
 Sophia Martinez

This post is a CLI-first, verification-grounded walkthrough through the `scrapeless-scraping-browser` cloud browser. Every selector, wait threshold, and failure pattern below is backed by an Ubuntu verification run on 2026-04-24 — Google-specific claims for organic extraction, pagination, localization, classic-SERP suppression, AI Overview polling, Knowledge Panel, PAA, and Related Searches.
 Alex Johnson

This guide walks through a terminal-first workflow on top of Scrapeless Agent Browser that handles the parts that normally eat weeks: anti-detection fingerprinting, residential proxies, dynamic rendering, and cross-marketplace locale consistency — all through a single `scrapeless-scraping-browser` CLI.
 Emily Chen

This guide shows how to install the Scrapeless Scraping Browser skill into 5 major agent environments, while keeping the same underlying browser foundation across all of them.
 Daniel Kim