• Agent Browser
  • Pricing
  • Docs
Loading Light/Dark Toggle

Products

Agent Browser

AI Scrapers

ChatGPT Scraper
Perplexity Scraper
Gemini Scraper
Copilot Scraper
Google AI Mode Scraper
Google AI Overview Scraper
Grok Scraper

Developers

Documentation
API Reference
Status

Legal

Privacy Policy
Terms of Use
Refund Policy
Don’t Sell My Info

Learning Center

Scraping Blog
Integration
FAQ
Glossary

© 2026 NST LABS TECH LTD.
All Rights Reserved.

All services are online

© 2026 NST LABS TECH LTD.
All Rights Reserved.

Contact us

Disclaimer : Scrapeless strictly adheres to the laws and regulations of each region, and we do not engage in any unauthorized access or data collection from private, confidential, or restricted sources

Web Scraping Blog

Most comprehensive guide, created for all Web Scraping developers.

Most Popular Articles

loading...
Contact our sales team
Monday to Friday, 9:00 AM - 18:00 PMSingapore Standard Time (UTC+08:00)

Scrapeless offers AI-powered, robust, and scalable web scraping and automation services trusted by leading enterprises. Our enterprise-grade solutions are tailored to meet your project needs, with dedicated technical support throughout. With a strong technical team and flexible delivery times, we charge only for successful data, enabling efficient data extraction while bypassing limitations.


Contact us now to fuel your business growth.

4.8
4.5
4.8
8.5
Book a demo

Provide your contact details, and we'll promptly reach out to offer a product demo and introduction. We ensure your information remains confidential, complying with GDPR standards.

Register and Claim Free Trial

Your free trial is ready! Sign up for a Scrapeless account for free, and your trial will be instantly activated in your account.

Sign up

Latest

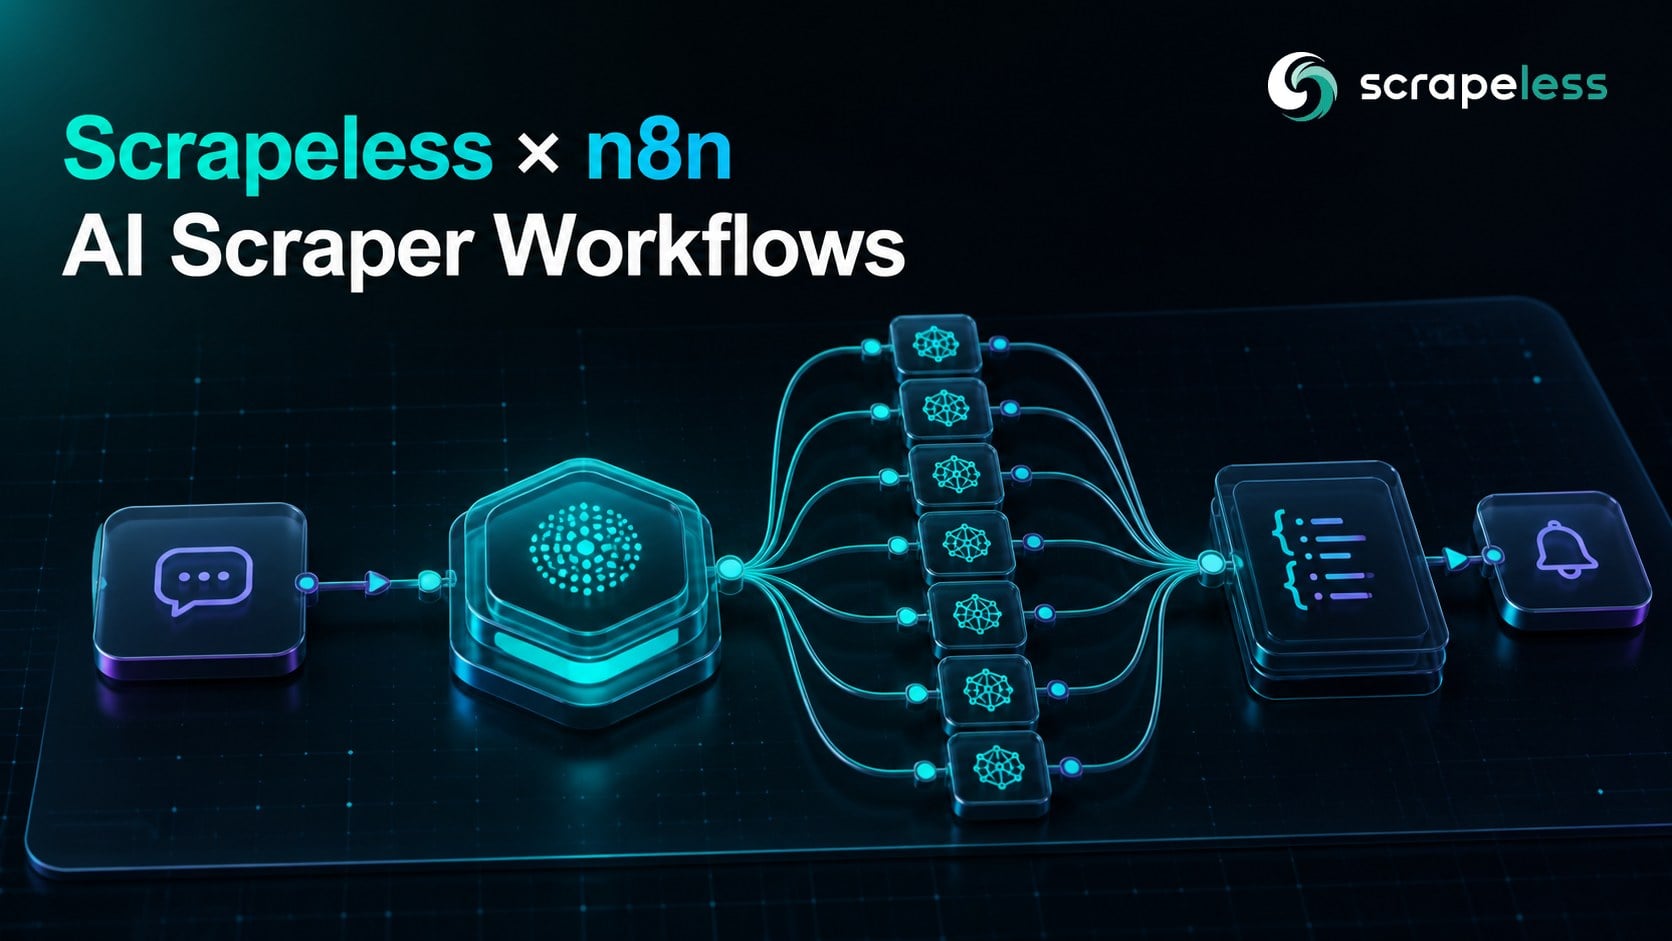
Scrapeless n8n Integration v0.5.4: AI Scraper Workflows
Scrapeless Official for n8n v0.5.4 adds seven AI Scraper actions. Learn how to configure them and build a multi-engine AI answer workflow.
07-Aug-2026
Scrapeless n8n AI Scraper workflow connecting seven AI answer engines to structured automation outputs.
TikTok Scraper API Guide: Profiles, Posts, and Shop Data
A practical actor guide for collecting and modeling public TikTok profile, post, and Shop product data with Scrapeless.
31-Aug-2026
TikTok scraper API workflow for profiles, posts, and Shop product data
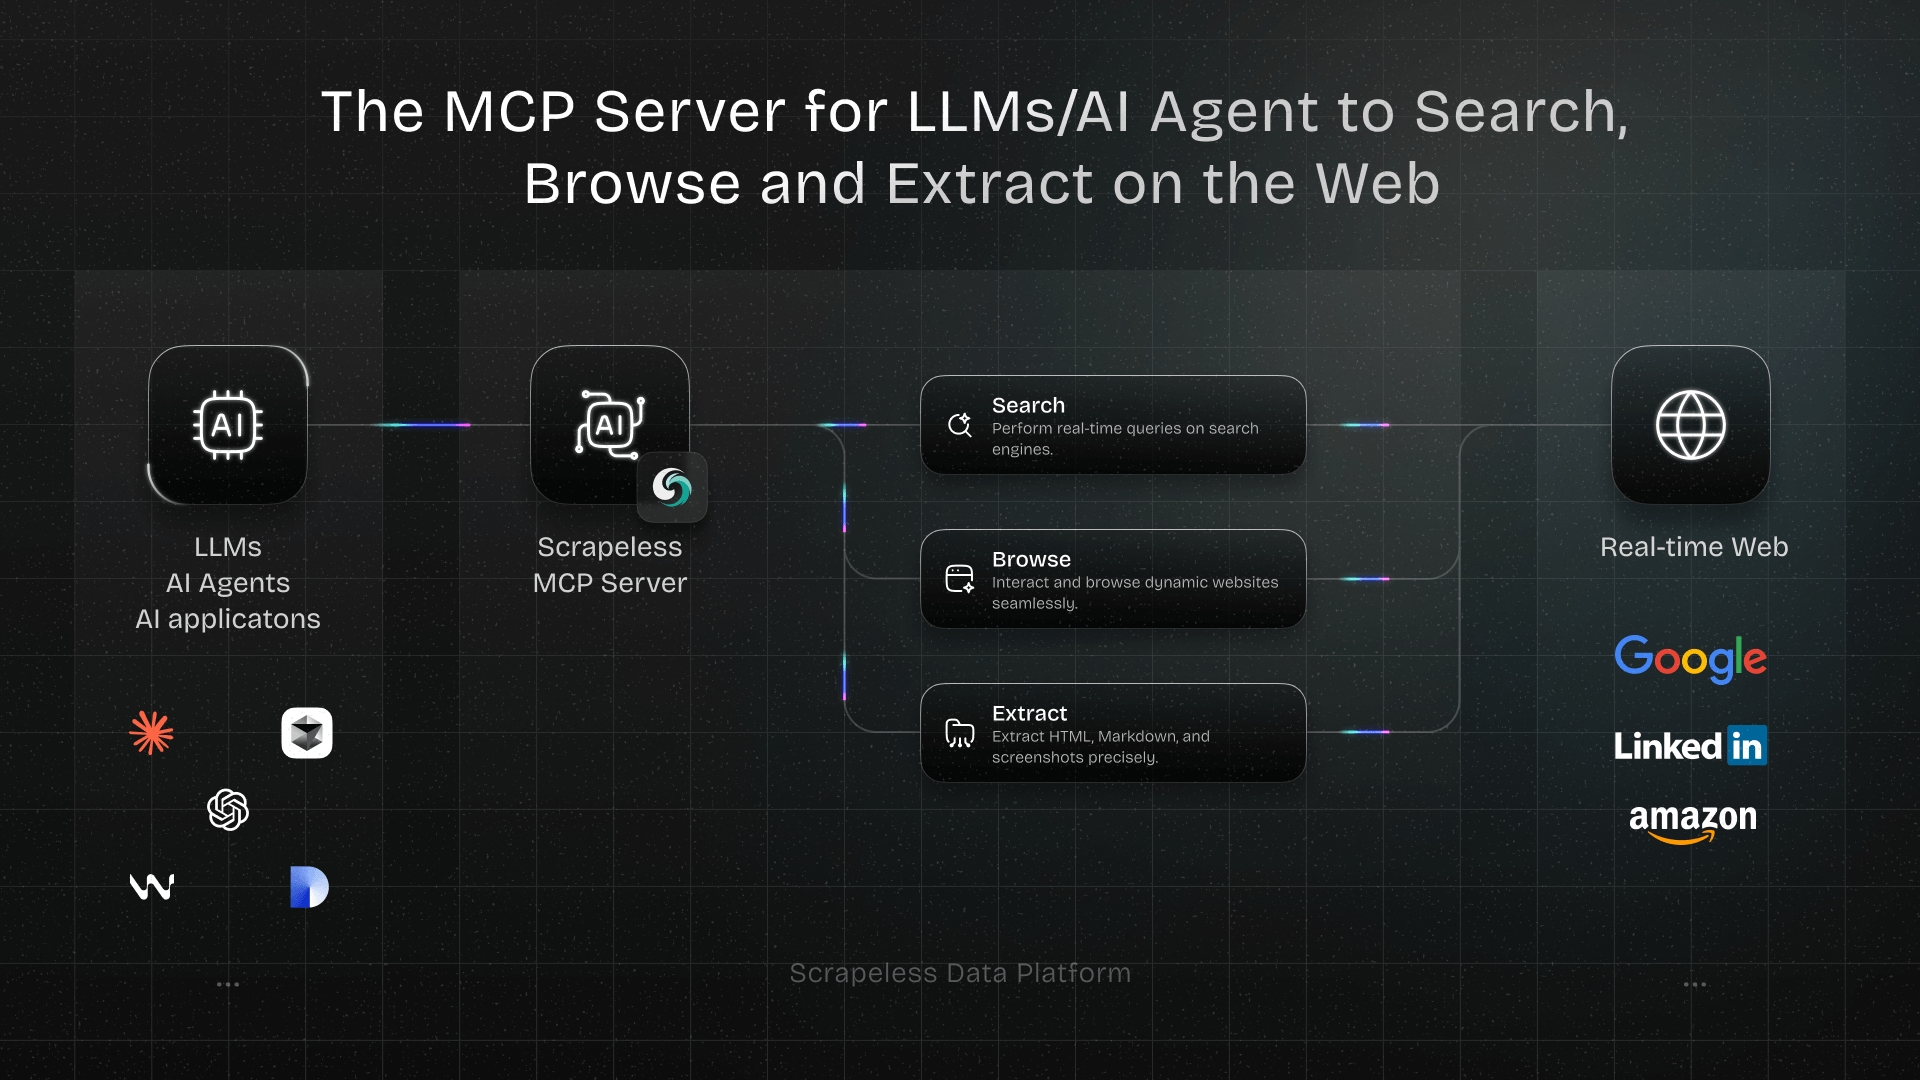
Scrapeless MCP Server Is Officially Live! Build Your Ultimate AI-Web Connector
Discover how the Scrapeless MCP Server gives LLMs real-time web browsing and scraping abilities. Learn how to build AI agents that search, extract, and interact with dynamic web content seamlessly.
17-Jul-2026
Scrapeless MCP Server

How to Add Web Search to Qwen Code: Scrapeless MCP Integration for Terminal Agents

This post closes that gap by wiring the Scrapeless MCP server into Qwen Code. One block in `~/.qwen/settings.json` gives the agent Google search, JavaScript rendering, and a full anti-detection cloud browser, all reachable through the same natural-language prompts it already takes for code.

Ava WilsonAva Wilson
25-May-2026
How to Add Web Search to Qwen Code: Scrapeless MCP Integration for Terminal Agents

What is SSL proxy and how it works

This guide defines the SSL proxy precisely, walks through the TLS handshake that lets it function, draws the line between forward and reverse deployments, and is honest about the security trade-off it represents. It closes with where managed proxy infrastructure fits when the goal is reliable data collection rather than running an inspection gateway yourself.

Ethan BrownEthan Brown
25-May-2026
What is SSL proxy and how it works

How to Build Production-Grade Web Scrapers with Scrapling and Scrapeless in Python

This tutorial builds a Python pipeline in two tiers. Tier 1 is Scrapling on its own — the right tool for static and medium-protected pages. Tier 2 routes Scrapling's `DynamicFetcher` through the Scrapeless Scraping Browser over CDP, so the rendering happens cloud-side behind residential proxies and per-session anti-detection fingerprinting while your Scrapling parsing code stays exactly the same. For the same Scrapeless Scraping Browser primitive driven through an agent framework instead of a fetcher, see the LangChain integration post.

Ava WilsonAva Wilson
25-May-2026
How to Build Production-Grade Web Scrapers with Scrapling and Scrapeless in Python

How to Build AI Agents That Scrape the Web: 8 Production Use Cases with Scrapeless MCP

The Scrapeless Scraping Browser collapses that gap. It gives an agent an anti-detection cloud browser — with residential proxies in 195+ countries and JavaScript rendering built in — exposed through the [Scrapeless MCP Server](https://github.com/scrapeless-ai/scrapeless-mcp-server) as a small set of composable tools. The agent itself does the scraping, in plain tool calls. Here are eight use cases that already work, each grounded in a real Scrapeless scraper.

Sophia MartinezSophia Martinez
21-May-2026
How to Build AI Agents That Scrape the Web: 8 Production Use Cases with Scrapeless MCP

Five AI Agent Use Cases for Web Scraping: YouTube, Maps, Amazon, Booking, Instagram with Scrapeless MCP

Five use cases, one toolset: each reduces to a single prompt that opens a cloud-browser session, renders the page, and returns structured JSON your agent can act on. The pattern is always discover, then extract — pin a proxy country close to the audience, keep the session work inside one prompt, and treat absent fields as nullable. Start with the use case closest to your goal, then reuse the same install for the next one. For deeper, step-by-step builds, see the Scrapeless MCP Server overview and compare plans on the pricing page.

Michael LeeMichael Lee
21-May-2026
Five AI Agent Use Cases for Web Scraping: YouTube, Maps, Amazon, Booking, Instagram with Scrapeless MCP

How to Stream Web Data Into Snowflake with Scrapeless and Snowpipe Streaming

This post walks through a terminal-first workflow that closes that gap. Scrapeless Scraping Browser handles the rendering and anti-detection side and emits NDJSON; Snowflake ingests it four different ways depending on how fresh the data needs to be. The example producer is the public scraping sandbox books.toscrape.com, so every command below is reproducible — the same pattern applies to harder targets (see the sibling Best Zillow Scrapers in 2026 and Best Amazon Scrapers in 2026 guides).

Alex JohnsonAlex Johnson
20-May-2026
How to Stream Web Data Into Snowflake with Scrapeless and Snowpipe Streaming

Best Zillow Scrapers in 2026: MCP-Native Agents vs Dedicated APIs vs Prebuilt Actors

For AI-agent Zillow scraping in 2026, Scrapeless is one of the strongest options thanks to its MCP server and cloud browser workflow, which closely matches real-world extraction: rendering pages in a US session, extracting `__NEXT_DATA__` JSON, and returning structured data for downstream pipelines. Other providers each have strengths in areas like ready-made datasets, AI-assisted parsing, scalability, or lower-cost extraction, but the core best practices remain the same: use US-based sessions, maintain session continuity, and follow a discover-to-extract workflow.

Ethan BrownEthan Brown
20-May-2026
Best Zillow Scrapers in 2026: MCP-Native Agents vs Dedicated APIs vs Prebuilt Actors

The Complete Guide to Web Scraping in Zencoder with Scrapeless MCP Server

This post wires the Scrapeless MCP Server into Zencoder through a single config block. After the wire-up, every Zencoder agent has 20 MCP tools mapped to a hardened cloud browser, a Google Search scraper, a Google Trends scraper, and one-shot HTML/Markdown/Screenshot helpers. The agent picks which tool to call per turn; the cloud browser handles JavaScript rendering, residential-proxy egress, and anti-detection fingerprinting; the IDE keeps owning the codegen, the file tree, and the terminal. For the same Scrapeless surface in Google Antigravity, see the Antigravity integration walkthrough; for the canonical MCP server reference, see the MCP server walkthrough for Google Maps.

Michael LeeMichael Lee
19-May-2026
d
Previous
52
53
54
Next